Try using the GitHub Copilot app >
|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> When an agent makes a change to your code, you want to review it, run it, and see what changed. Great news: now you can do all three without having to leave the GitHub Copilot app . Before, doing those three jobs would mean having to bounce between your editor, terminal window, and web browser. But when these steps live side by side as built-in panels in the Copilot app, checking your agent’s work is simple. Let’s walk through each of the panels in the app and how we’ll use them to complete the AI coding loop. Using the diff panel to review changesThe diff panel (a diff is a before and after comparison) shows exactly what lines were added, removed, or changed, with additions highlighted in green and deletions in red. This gives you complete clarity, so you can choose what happens. You can accept changes, leave comments, or ask Copilot to make changes. You’re in complete control and make the final decisions. Running commands in the terminal panelReading code is good, but running it is even better. You can run commands right inside the session from the Copilot app’s terminal panel. And if it looks intimidating, don’t worry. You’re mostly just running the project’s own commands and reading the results. You can run the code by hand or configure it as a script (available through the Run button). Pretend you’re working on a website, here’s an example of how that works:
You can have multiple terminal windows open at once, so you can switch between them and keep running commands. Using the pick & polish tool in the browser panelFor anything that has a user interface, the browser panel closes the loop. And for our website example: this panel means you can open it and test your new feature as if you were using the site. If you want to keep iterating, you can use the Pick & Polish tool to select an element and adjust it with the agent.
And to see what got fixed, you can run the Closing the loop of reviewing AI codeNow you’ve reviewed the diff, started the project in the terminal, reviewed it in the browser, and iterated to get it to a working feature. Once you’ve gotten it where you want, you can accept the change directly from the Copilot app and create a pull request. Completing this loop from one place means there’s no tab hopping, switching apps, or losing your place. Having review, run, and preview side by side is what makes agent-made changes feel safe instead of scary, because you can prove that what you’re merging works. Take this with youThese built-in panels answer three important questions you should always ask before you accept an agent’s work.
Running through this list before accepting agent-generated code will help you understand what changed and whether it functions the way you want, keeping you in control. ✨ |
|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> While we continue to make progress, August proved to be a challenging month for availability. You can read more about these incidents in a blog post we published last month. We are aggressively investing in both architectural improvements and moving to Azure, which will give us more capacity. Meanwhile, we continue to see significant growth on our platform. We are prioritizing the most impactful work while minimizing risk, but as these incidents in August show, we cannot completely eliminate risk. Ultimately, all the work needs to be done, and incidents give us an opportunity to adjust our priorities. As repair items from these incidents, we’ve made significant improvements to our capacity monitoring and management, retry policies that led to bigger impact, and resiliency improvements to core services. We’ve also continued to make great progress across many durable work streams. On August 11, GitHub ran a production MySQL primary from Azure for the first time. Client-observed write impact was minimal, and no customer impact occurred in the transition. We repeated the pattern with two more primaries on August 27. We have further primaries scheduled over the coming weeks, increasing in complexity as we learn from each failover. Read traffic also reached new highs. Reads from migrated services peaked at 60.4%, while reads from GitHub’s monolith peaked at 64.3% in Azure. Git reads reached 54%. Away from the regional migration, the 24-table authentication-core cohort moved off GitHub’s oldest shared database, mysql1, removing approximately one million queries per second from its replicas. Separate query-hygiene changes removed another 120,000 queries per second and eliminated approximately 59,000 seconds of wasted database work per hour. GitHub Actions gained additional capacity while longer-term isolation work continues. Job-routing changes moved 33% of jobs from a constrained production cluster to spare capacity, reducing peak cache CPU utilization from 98% to 80% and adding an estimated three months of headroom. This is a near-term containment measure, not the finish line; the August outage reinforced the need for more durable capacity and isolation, which continues. Pull request isolation work continued. In addition to unauthenticated traffic already being served, now authenticated reads for the first production cohort reached 100%. Investments in Git overload protection served 6.4% more traffic while improving 95th-percentile duration by 24% and maximum delay by 78%. Broader load-shedding protections at the edge also made progress, enabling levers that can protect GitHub under unexpected load—in fact, these protections were used in mitigating the aforementioned incidents in August. We also improved monitoring and telemetry. Pull request monitoring now measures merge, review, and comment failures independently, where high read volume could otherwise mask a failing write path. On August 21, automated high impact incident detection began combining customer-support signals with service telemetry. API monitoring was also recalibrated and validated over 30 days, reducing noise and improving signal quality. These changes improve detection and response. The next month of work includes moving the next database primaries, continuing to migrate services and corresponding traffic to Azure, chipping away at database health particularly on shared-databases, adding more automation around capacity management and auto-scaling, and extending dependency-failure handling across more of the pull request experience. This principle continues to guide us: availability, then capacity, then features. August 06 15:22 UTC (lasting 10 hours and 42 minutes)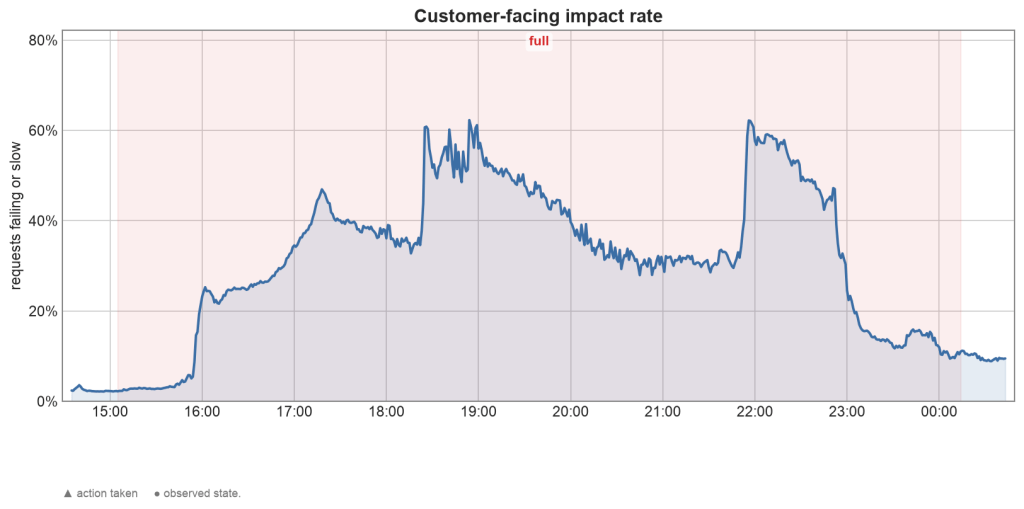
What happened?The incident began with a routine deployment to an internal GitHub Actions service that processes incoming events and turns them into actions jobs. The deployment’s contents were not at fault (we rolled it back to confirm this); instead, replacing pods during the rollout briefly reduced capacity in one site and pushed the remaining sites past their limit as traffic shifted to them. Impact was heaviest through the middle hours of the incident, when a large share of actions workflow runs were failing to start or complete. What went wrong and why?The affected actions services were running close to their capacity and concurrency limits. A routine deployment that briefly reduced the number of running pods was enough to exhaust available headroom. This caused service mesh sidecars to experience CPU throttling and out-of-memory restarts, which then cascaded into cache, DNS, and API errors across multiple clusters. The ingress service mesh for these services had limited headroom so it could not absorb the temporary loss of capacity during the deployment. As the core services recovered, a latent bug in the job-assignment path made recovery slower: runners were handed jobs that had already been revoked, then got stuck retrying them instead of picking up valid work, which created a self-amplifying backlog. How did we respond?
How are we making incidents like this less likely or less impactful?
August 17 13:40 UTC (lasting 7 hours and 35 minutes)What happened?What went wrong and why?A new peak in traffic pushed one datacenter’s load balancers past their limits. A service-mesh sidecar reached its concurrency limit and did not scale up. As requests backed up, several of the datacenter’s load-balancer nodes exhausted their network flow limits, which degraded the shared gateway authentication path and produced widespread authentication latency and failures across the many services that route through that datacenter. A latent client retry bug sharply amplified traffic to one internal authentication endpoint, which slowed recovery for the Copilot Token Service. The core weakness was that our service-mesh sidecar did not scale up, together with our retry behavior, and clients were not bound enough to keep a partial degradation from amplifying into a broader overload. How did we respond?
How are we making incidents like this less likely or less impactful?
August 20 14:43 UTC (lasting 9 hours and 54 minutes)What happened?During the incident window, the Copilot cloud agent task was impacted. The tasks themselves still ran to completion, so no work was lost. Once processing caught up the correct status and results appeared. Waiting a short time, or checking back a little later, would have shown the up-to-date state. Across the incident, at least 54 organizations experienced Copilot Cloud Agent task status and results lagging well above their own normal level. Per-minute customer-facing impact peaked at 37.5% of measured task-status activity. What went wrong and why?Copilot cloud agent stores the status and results of each agent task in a managed cloud database. One region of that database suffered a provider-side outage, and the calls that read and write task status in the affected region began failing and running slow. The processors that stream task-status updates into that database then fell behind as database latency climbed. Their throughput is bounded by a fixed number of processing partitions sized for normal latency plus some headroom. The latency in this incident went well past that headroom, causing the backlog of task-status updates to grow instead of clearing. A storage configuration on the database also made the affected region slow to fail over, so the first failover attempts did not take effect, and recovery took longer than expected. How did we respond?
How are we making incidents like this less likely or less impactful?
August 26 15:11 UTC (lasting 2 hours and 50 minutes)What happened?Dependent services like Copilot code review and some GitHub Pages deployments that run on top of actions, were impacted during the incident window. In most cases, delayed runs started once the backlog drained, and runs that failed to start succeeded when re-run after the incident. A small set of runs that were created during the earliest part of the incident could not be recovered by re-running and had to be started fresh. What went wrong and why?The quick summary is that our shared infrastructure services have not kept up with our month-over-month actions growth and peak load. A burst of incoming events arrived on top of an already-high load and pushed the database past its tipping point. Query times climbed, and the database primary saturated. With the database overloaded, the internal service that turns incoming events into runner assignments could not keep up, so actions runs failed to start and began queuing well past their normal start time. Failing over the database primary helped only partially. The throttles used to relieve inbound load were initially set slightly too high to fully protect the database, so recovery had to be ramped up slowly and manually. There was no automatic circuit breaker to throttle inbound actions load when the database showed early signs of stress, so the protective throttling had to be applied and tuned manually during the incident. This is one of the learnings from this incident. How did we respond?
How are we making incidents like this less likely or less impactful?
August 27 10:04 UTC (lasting 2 hours and 8 minutes)What happened?Customers who had configuration to use the Kimi K3 model were impacted by this incident. Customers who were using other models or switched to using other models were not impacted. What went wrong and why?Copilot offers a choice of AI models. One of them, Kimi K3, is served by an upstream model provider. That provider had a serving degradation that caused a large share of Kimi K3 requests to fail with errors. Because the problem was with the upstream provider, requests that used other models—and requests made with the Auto setting, which routed to a different model—were not affected. A steady share of Kimi K3 requests kept failing until the provider’s mitigation took hold. At peak, more than half of the requests using Kimi K3 were failing. How did we respond?
How are we making incidents like this less likely or less impactful?
Follow our status page for real-time updates on status changes and post-incident recaps. To learn more about what we’re working on, check out the engineering section on the GitHub Blog . The post GitHub availability report: August 2026 appeared first on The GitHub Blog . |
|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> Providing developers the best model for the task at hand has always been our goal. Earlier this year, we made that easier by launching Auto model selection, which reviews your task and matches it to the best-suited model for that task. Today, we’re introducing Project HydraFusion, a research preview that delivers frontier intelligence through runtime orchestration. It creates a full execution plan, choosing from models across multiple providers to draft, critique and revise, or cascade to more powerful models to complete your task. HydraFusion fills a key role in our overall strategy to deliver automated semantic routing between local, cloud, and compound models. For developers, that complexity stays behind the scenes: you select HydraFusion like any other model, and it chooses a workflow that balances performance, cost, and latency for each task. HydraFusion treats workflow selection as an optimization problem. It uses capability signals for reasoning, code generation, debugging, and tool use to select the most efficient execution pattern to meet the quality bar. For each request, HydraFusion currently chooses one of three execution patterns:
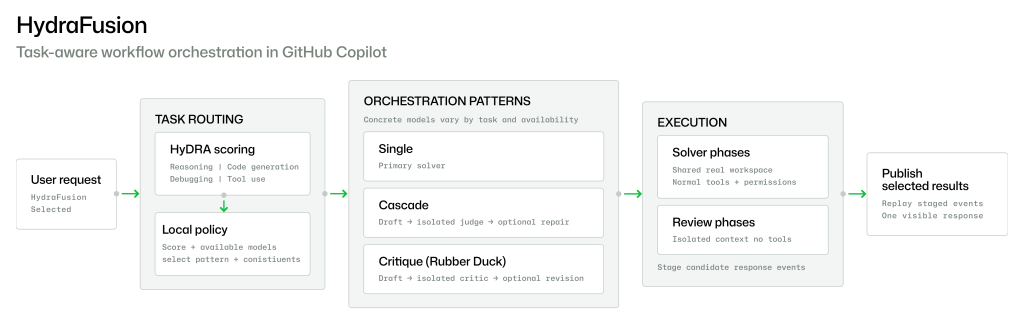
Each pattern addresses a different quality-to-cost trade-off. Single preserves speed and efficiency when one model can solve the task directly. Cascade gives an efficient model the first attempt while retaining a path to stronger inference when the candidate does not clear the acceptance gate. Critique adds an independent perspective for tasks where review is more useful than another unaided attempt. In offline evaluations across three agentic coding benchmarks, HydraFusion consistently demonstrated frontier-level quality with substantial estimated cost savings. On TerminalBench 2.1, it improved verified task quality by 4.9 percentage points at 67% lower estimated cost compared with Claude Opus 5. Let’s dive into the approach, the results, and the benchmarks. Adaptive multi-model orchestrationDevelopers already coordinate models manually: choosing one for a task, asking another to review the work, or escalating a difficult problem to a more capable model. HydraFusion brings that familiar process into the runtime. You choose HydraFusion once and stay focused on your task while it manages the models and workflow behind the scenes. The key is selectivity. Some coding tasks can be solved directly, while others benefit from review, revision, or escalation. HydraFusion evaluates each request and chooses the least complex workflow expected to meet its needs, using additional model calls only when they are likely to improve the result. This adaptive approach balances quality, cost, and latency across models. As the model frontier advances, so does HydraFusion. When new models become available in GitHub Copilot, we can evaluate and incorporate them into its model pool, bringing their strengths to the tasks best suited to them. Building HydraFusionTurning adaptive multi-model orchestration into one dependable coding experience requires careful control of execution, review, cost, and repository state. HydraFusion is built around five operating principles:
Together, these principles make multi-model orchestration practical for repository-level work. Internally, the runtime records the role, outcome, cost, latency, and diagnostics of each leg so the workflow can be understood after execution. Externally, the developer receives one coherent response and one permission-aware change set. Benchmarking results
Fixed HydraFusion policies were evaluated across three agentic coding benchmarks — TerminalBench 2.1, DeepSWE, and CheckpointBench, our internal benchmark based on real GitHub Copilot sessions — using Claude Opus 5 and GPT-5.6 Sol as comparison baselines. Each policy used the same task inputs, tools, execution limits, pricing assumptions, grading conditions, and treatment of missing results. The evaluation measured verified task quality, which is the share of tasks confirmed as correctly answered, and the complete estimated workflow cost. Cost accounting included every invoked leg, such as drafting, critique, revision, escalation, retry, and fallback. The results below show the best tuned HydraFusion configuration.
These controlled offline results are specific to the evaluated benchmark revisions, workflow configurations, model pool, and pricing assumptions, with all models evaluated at the same medium reasoning level. Through this research preview, we’ll validate how these results translate to real developer workloads and use the findings to further optimize HydraFusion for production quality, latency, reliability, caching efficiency, cost, and safety. TerminalBench 2.1TerminalBench 2.1 evaluates coding agents on complex, multi-step tasks in terminal environments. Figure 2 compares HydraFusion and Opus 5 across verified task quality and estimated workflow cost. DeepSWEDeepSWE evaluates challenging repository-level software engineering tasks that require navigating large codebases, understanding cross-file dependencies, and producing end-to-end fixes. On this benchmark, HydraFusion comes within 1.5 percentage points of Opus 5 while reducing cost by 36%, demonstrating a compelling quality-cost tradeoff for complex real-world engineering tasks. CheckpointBenchCheckpointBench is an internal multi-turn benchmark curated from real GitHub Copilot agentic coding sessions. Each conversation is anchored to a specific public repository and immutable commit, ensuring every session is replayable. The benchmark is balanced across language, task type, difficulty, scrubbed for quality, resulting in a realistic evaluation set that closely mirrors production agentic sessions. On this benchmark, HydraFusion comes within 0.1 percentage points of Opus 5 at 65% lower cost. Early internal testing has echoed that result.
Hill-climbing HydraFusionHydraFusion’s routing policies were shaped by how developers use GitHub Copilot on real coding tasks. To make those workflows reproducible, we curated CheckpointBench from real Copilot coding-session trajectories. We refined HydraFusion repeatedly across CheckpointBench, DeepSWE, and TerminalBench 2.1, optimizing across the evaluation sets rather than for any single benchmark. HydraFusion’s per-capability scores provided a consistent basis for comparing candidate routing policies. Instead of manually tuning thresholds, we used beam search to build the optimal decision policy. Each candidate was measured against a frozen baseline on quality, cost, and failure modes, so improvements were evaluated on stable ground. TerminalBench 2.1 provides the most complete sequence of runs, making it the clearest view of this iterative improvement. The progression was not linear. Between August 11 and August 25, two operational failures in the evaluation harness produced invalid runs. Those failures were excluded from the performance trend, corrected, and followed by continued gains in the HydraFusion configurations. By August 25, HydraFusion had reached its strongest operating points in the recorded series. This development record shows how the policies improved from repeated experiments. TerminalBench 2.1 was one of several benchmarks used during development. Its relative saturation makes broader validation important, so the three-benchmark evaluation also includes DeepSWE’s more demanding repository-level tasks. The research preview extends that learning loop to real developer workloads. Try the research previewFor this preview, first-turn, single-prompt coding tasks are the best place to start. We’ll be focusing on strong multi-turn performance with longer, iterative sessions next.
This preview is designed to learn which tasks benefit from compound workflows and how orchestration affects latency and cost in practice. For the best experience today, start with substantial, well-scoped coding tasks that you can hand to Copilot in autopilot mode in a single prompt. Share what you find, including where it excels, where it falls short, and what you’d want to see next, through HydraFusion remains an active research effort. Results, models, workflows, availability, names, and product behavior may change as we learn from the preview. We believe the next real gain in coding agents will come from combining frontier intelligence with runtime orchestration. HydraFusion is our first bet on that idea: moving from choosing the best model to dynamically constructing the best way to solve each task. AcknowledgmentsA huge thank-you to the researchers, engineers, product managers, and designers across GitHub and Microsoft who curated the training data and built the training pipeline, evaluation suites, client experience, and serving stack. We are especially grateful to the GitHub Copilot CLI, Copilot API and VS Code team for overcoming numerous challenges to bring this research preview to our customers. Meet the Team
The post Project HydraFusion: Frontier quality via multi-model orchestration appeared first on The GitHub Blog . |
|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> Running multiple AI agents on the same project seems like pure chaos, with too many cooks in your development kitchen. But with the GitHub Copilot app , these agents work separately and don’t interfere with each other, allowing you to get more done in less time. Think of parallel agent sessions like a trip to the laundromat. You can start multiple loads of laundry at the same time, in their own machines. You can set each washer with its own settings, and it won’t impact the other loads. Most importantly, you don’t have to wait for one to finish before you can start another one. Let’s look at how it works. Agent sessions, Git worktrees, and contextAn agent session is a task you’ve given Copilot, start to finish. In the GitHub Copilot app, you can manage several sessions through the sessions view. Each card shows its title and how far along the agent is in completing its task. Each session runs independently of the others. That means you can start a new session whenever you want, and the ones already running won’t be disturbed. But here’s where the real magic happens. Each agent session in the GitHub Copilot app can run on its own Git worktree. Since each session is isolated, they can run in parallel, all at the same time. That means you spend your time reviewing and making decisions rather than watching your agents at work. Plus, each session keeps its own context, so you can switch between them freely. Each picks up exactly where you left it, and you never have to re-explain what you were doing. Less context switching means you feel less scattered. What this looks like
Let’s look at an example repository, The first step is to ask Copilot to build the funded sort feature. Just as it gets started, open a new session and ask Copilot to perform an accessibility review. As that gets under way, start prompting Copilot to run some tests in a third session. In the session view, you can keep track of all of these as they progress and review the results as they finish. Or you can step away entirely, grab a cup of coffee, and know your work is happening without you babysitting it. Get startedReady to feel the power of parallel agent sessions? Try starting two small tasks at the same time in the GitHub Copilot app . It’s a low-stakes way to watch your tasks progress independently. Start using the GitHub Copilot app > |
|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> It might be overwhelming to see all of the new vocabulary popping up in software development these days thanks to AI tools introducing them… all the time. Some of this new vocab describes useful patterns that people are newly pursuing, others are just fancy names on top of things that already exist, and some are still actively being defined as we speak. In our latest episode of the GitHub Podcast , Marlene Mhangami, GPS, and I talked through some of the AI terms developers are learning right now: loop engineering, Ralph loops, squads, harness engineering, hill climbing, forward deployed engineers, closed models, open weights, and open source models. If you’re a reader instead of a listener, here’s a guide to what those terms mean, why they matter, and how to think about them. Listen to the full episode below! 👇 Loop engineering: Moving beyond one-shot promptsLoop engineering is the practice of designing repeatable systems around agents, instead of manually prompting them for one task at a time. A simple example: instead of asking an agent every morning to review new issues, summarize them, and propose fixes, you create a loop that runs on a schedule. That loop might fetch issues, pass them to an agent, validate the output, and escalate anything that gets stuck. It’s a glorified AI-native cron job. Ralph loops: The brute-force cousin of loop engineeringA Ralph loop is one implementation of this “loop” concept: you give an agent a detailed task, often from a product requirements document or spec, and have it keep working until the job is done. That can be useful, especially for breaking down large tasks into repeated plan-act-check cycles. But, on the other hand, it can also be expensive and inefficient because every iteration uses more tokens, more context, and more compute. Loop engineering aims to make this pattern more structured, so you’re not caught asking an agent to “try again” all the time. A well-designed loop adds primitives like skills, observability, validation, routing, and checkpoints. Squads, fleets, and multi-agent workflowsIf loops define a workflow, “squads” and “fleets” describe how multiple agents can participate in that workflow. A squad is a group of agents with different roles. They often reflect a real-world team. One agent might plan, another agent might vet that plan, another agent might implement it, another might test it, and another might review it. A fleet refers to parallel agents working on tasks at the same time. You can have a squad working in a fleet in parallel, or in a sequence. Operating this way lets different agents handle different parts of a process, and you can fine-tune and specialize each one with specific skills to be more efficient. The core idea is parallelization and specialization. Instead of one agent trying to do everything, different agents can handle different parts of a development process. Harnesses: The system around the modelOutside of what a model generates, a harness is everything surrounding it that makes it useful in your workflows. That could be the tools, permissions, memory, context, orchestration (and so on) that guides how the model behaves. If it helps you remember: harnesses are aptly named after the harnesses for horses. Horses are like models that can run wild, and a harness helps direct the horse’s weight safely as it completes tasks. Get it? Anyway, a good example of a software harness is GitHub Copilot. It connects models to codebases, editors, pull requests, terminals, and so on. When you hear the term “harness engineering” tossed around, that’s the work of designing and improving that system that surrounds the models. Hill climbing: Improving agents with feedbackThe term “hill climbing” is used to describe the process of improving agents and harnesses over time. That could mean, for example, using evals to measure whether an agent is producing the right kind of output (and then adjusting the harnesses until the results improve). Or, another example, if your agent is supposed to review pull requests, hill climbing might be checking if it indeed finds meaningful bugs and produces useful recommendations, and adjusting tooling to improve that. Forward deployed engineer: A familiar role with an AI focusA forward-deployed engineer job has already existed, but AI branding makes it sound edgy and new. Now, it’s a customer-facing software engineer, or sales engineer, or solutions engineer, often with an AI focus. If you haven’t seen those job titles before, this person generally works closely with customers to implement or adapt technical solutions into their environments. With the AI focus, that means helping teams integrate AI tools, workflows, agents, etc. into their existing systems. Closed models, open weights, and open source modelsNot all models are shared in the same way. Closed models are accessed through an API or hosted product. Developers can use the model, but they don’t get access to the underlying weights, training data, or training process. The big, famous frontier models you hear about are often all closed models. Open weight models make the model weights (which are like dials that decide how important certain inputs are) available. Developers can download and run these models, often locally or in their own infrastructure. But, to be clear, the dataset and training method may not be fully available. Open source models go a step further, in that the model, code, data, and training process are all available for inspection, reuse, and modification. The more open the model, the more you can run, customize, audit, and trust it. The terms are ever-evolvingThis is just a sampler of some of the terms we’re hearing a lot today. Some will stick around, and others will fade into our memories, and others will be replaced by better language as the industry matures. Don’t worry about falling behind on buzzwords. They’re just words, and more important are the practices under them! Ask yourself if workflows can repeat reliably, how you validate tasks, how humans should (or shouldn’t) interfere, how much you can rely on a model, and how you can improve that your system. It’s a new era of engineering, and best practices still matter! Subscribe to the GitHub Podcast so you never miss an episode! |
|
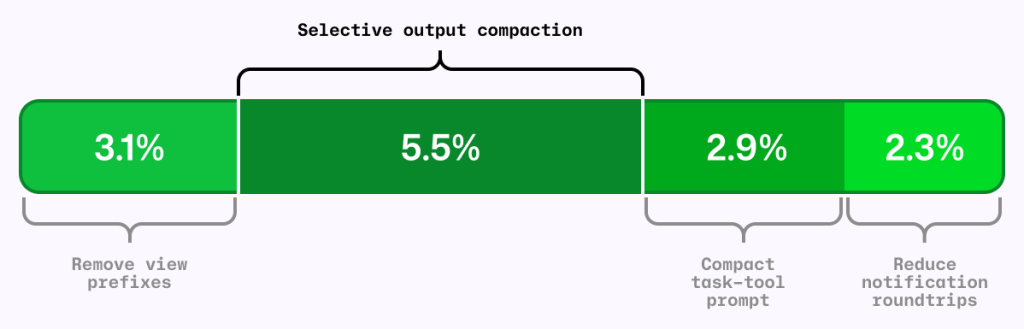
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> Output quality is important when working with AI coding agents, but true efficiency comes from getting work done quickly, efficiently, and with the right context. That’s why token count of individual interactions alone isn’t a meaningful measure of efficiency. The goal shouldn’t be to use fewer tokens, but to tap into the right amount of context to move a task forward. A concise tool response can sometimes require additional calls or work if it leaves out information the agent needs, ultimately making the task slower and more expensive. That’s why we want to optimize for the outcome rather than the tool call. This post examines four changes in GitHub Copilot that put that principle into practice:
Possible changes were evaluated offline using agentic coding benchmarks. The most promising changes were then validated through controlled online experiments before shipping. The examples in this post come from GitHub Copilot CLI. Multiple other Copilot products, such as the GitHub Copilot app and Copilot code review, use the same underlying harness and also become more efficient through these improvements.
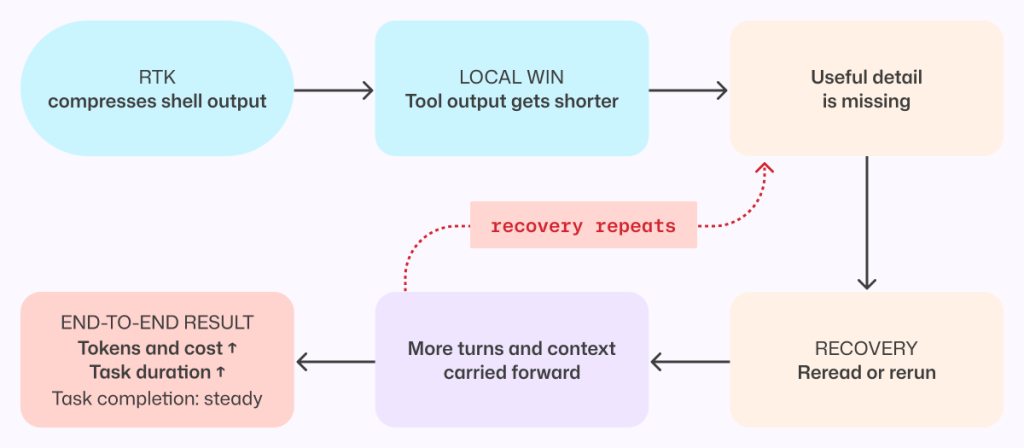
The local metric trapIt’s common to shorten the output from each tool call as a way to reduce agent costs. RTK (Rust Token Killer) is a utility that shortens shell output before an agent reads it. We evaluated its effect on GitHub Copilot using our agentic coding benchmarks. In our harness and benchmark configuration, RTK shortened some responses, but when the omitted text mattered, the model sometimes reopened the original output or reran the command to recover what it needed.
Those recovery steps added turns and carried more context forward. The individual tool response was shorter, but on average, the task used more tokens and took longer. We saved tokens locally and spent more globally.
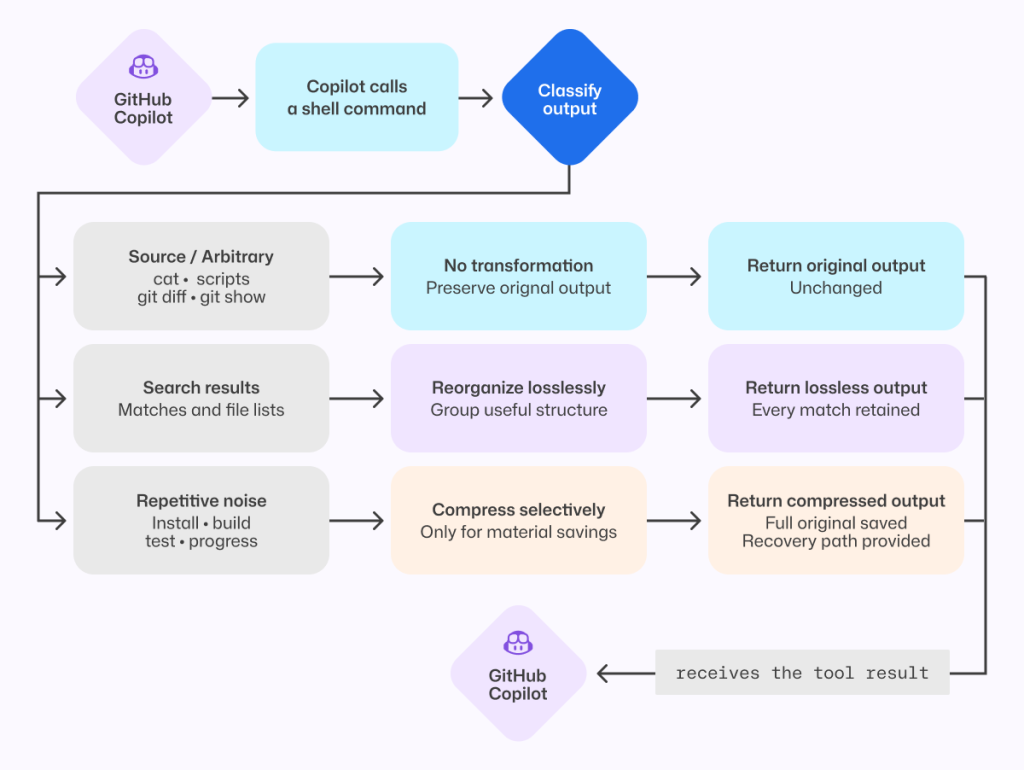
This result applies to the integration and workloads we tested, not to every RTK configuration or to output compression in general. This meant that tokens per tool call is the wrong objective. An efficiency change has to be evaluated across the complete task, from the user’s request through the final result. More useful was to look at what can we remove without making the model repeat work. Compress noise, preserve useful informationThe goal was to shorten repetitive output while preserving the context an agent needs to complete its task without retracing steps. Analysis of benchmark runs showed that install, build, test, and lint output often contains repetitive noise, while source-like output and arbitrary command results are more likely to contain the information an agent needs. That analysis informed a selective output compressor, informed in part by RTK and similar approaches. The prototype was evaluated on agentic coding benchmarks and a range of open source repositories, exercising their build, test, and lint systems.
Early versions were too aggressive. They made the model repeat work or read the full saved output, increasing end-to-end cost and reducing task success. For example, we initially compressed Those early failures led to a three-part policy:
The shipped version emerged through repeated evaluation and refinement. It is conservative not because the goal was to build a conservative compressor, but because that is what the evaluations supported.
When output is compressed, the agent can still retrieve the complete original through a direct recovery path.
That recovery path is both a safety mechanism and an evaluation signal. We tracked whether the agent opened the saved original, reran commands, repeated exploration, narrowed its searches, or took additional turns. Frequent recovery would indicate that the compressor had removed something valuable. On offline tasks where output compression triggered, no statistically significant task-success regression was detected, and agents extremely rarely opened the saved originals. In the online experiment, average cost decreased slightly with no material regression detected in the tracked quality metrics. Remove formatting before removing information
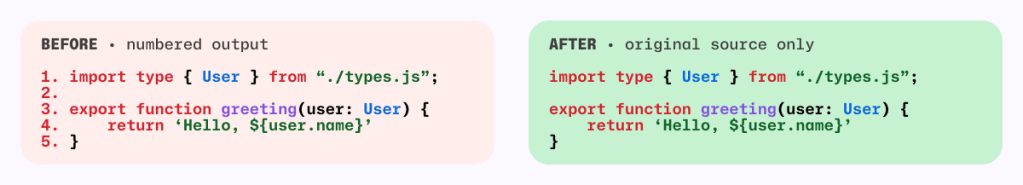
One clean token optimization came from the
Previously,
Each prefix was small. Repeated across every line and every file read, however, that unused formatting accumulated throughout a session. So, we removed it.
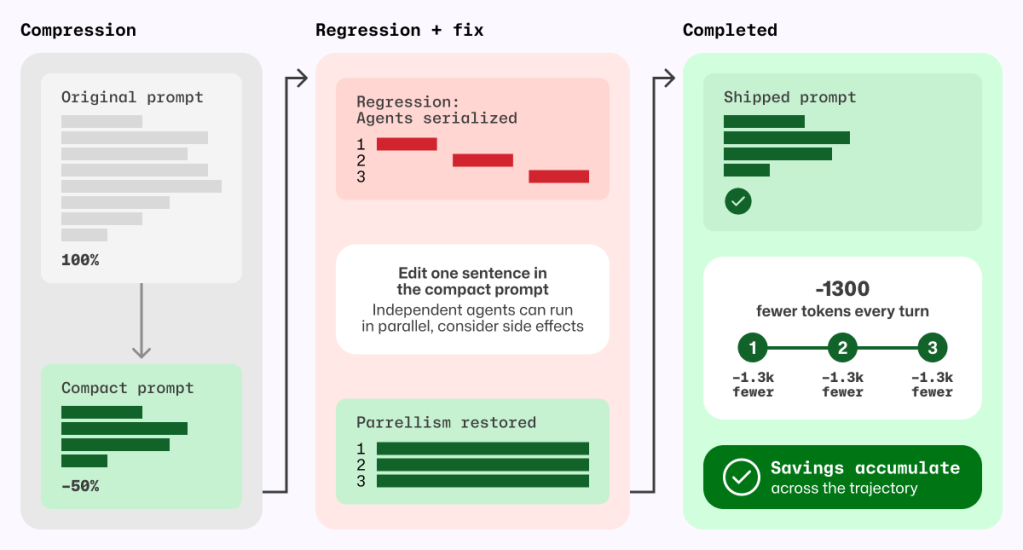
Line numbers remain useful in diffs and short snippets. They were wasteful here because they were attached to every file read without serving the current editing workflow. Removing them caused model-inference cost to fall by roughly 5% in offline agentic coding benchmarks. Success rates stayed within the expected run-to-run variance, and edit failures did not increase. We then tested the change with Copilot CLI users. The online experiment reduced average daily model-inference cost per user by about 3%, with no material regression detected in the quality or satisfaction metrics we tracked. For developers, that means more of the context window is available for the work itself rather than formatting the agent does not use. This was the ideal change: no new instructions for the model, no source of information to recover, and no additional decision to make. The file contents reached the model unchanged. Compress prompts without compressing intentPrompts carry instructions that shape how an agent works, and they are sent to the model on every turn. Shortening them only improves efficiency if the agent keeps the behaviors developers depend on. In GitHub Copilot, the task tool launches specialized agents for parallel work. Its guidance had accumulated across tool descriptions, schemas, agent definitions, system instructions, and companion tools. A meta-prompting loop, in which Copilot iteratively wrote its own prompt, reduced that prompt by roughly half. Copilot produced and refined smaller candidates, and targeted behavioral tests checked the requirements we wanted to preserve. The first online experiment found a regression that the initial offline evaluations had missed. The meta-prompting loop had rewritten cautious parallelism guidance into a hard scheduling policy, causing independent custom agents to run sequentially. We stopped the experiment. Before changing the prompt again, we wrote a regression evaluation for the behavior users had exposed. The eventual fix replaced an explicit allowlist and denylist with one sentence: Independent agents can run in parallel; consider side effects. That sentence was shorter and less restrictive; it deferred the choice of whether to run sub-agents in parallel to the model instead of the previous explicit guidance. With it, our new behavior test passed without causing any existing behavioral tests to fail.
Prompt behavior needs tests. If a behavior is not tested, a shorter prompt can remove it without anyone noticing.
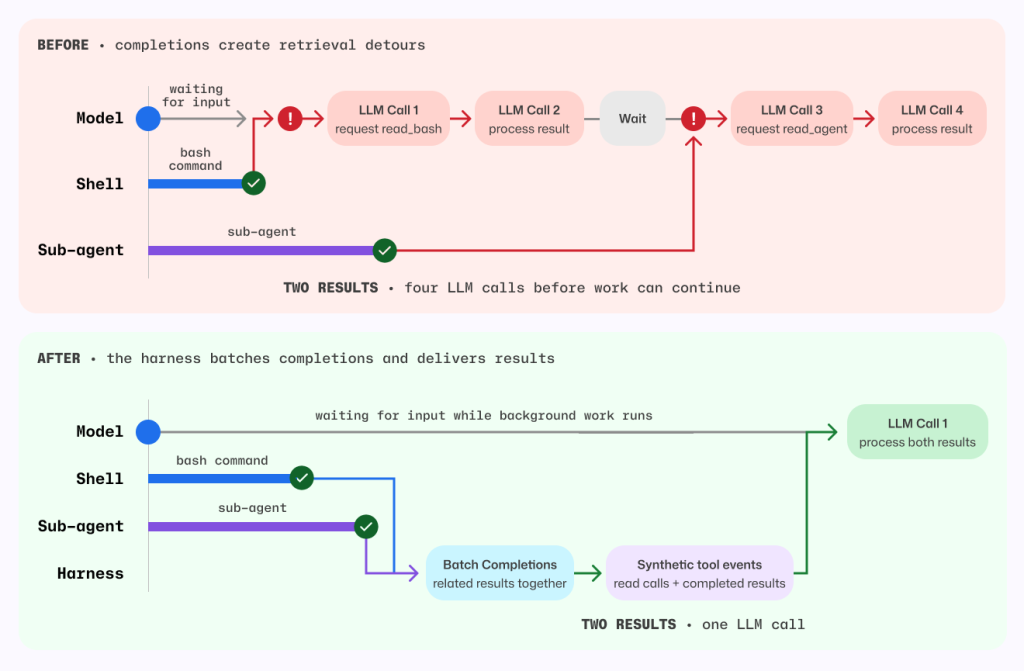
The shipped prompt removes about 1,300 Deliver completed background work without an extra retrieval turnAgents often run independent work in the background, such as a long-running shell command alongside a sub-agent investigation. Notifications let the agent continue until that work is ready without spending a tool call waiting. If the agent does not explicitly wait for either task, the harness wakes the model and notifies it when the shell command or sub-agent finishes.
Previously, that notification did not include the completed result, so the agent had to spend another turn retrieving output Copilot had already received. When several tasks finished close together, that detour could repeat. Copilot now batches eligible completion notifications and delivers completed results directly in the existing tool-result format. The agent can continue with the information it needs, without spending an extra turn asking for it again. Explicit reads for work that is still running behave as before.
Before this change, each completed task required one model call to request its result and another to process it. For the shell command and sub-agent shown above, that meant four model calls before work could continue. Now, the harness batches both completions and supplies their results together, so a single model call can process both. Removing those retrieval detours also avoids carrying the full session context through unnecessary calls. By delivering completed results directly, without compressing, summarizing, or withholding anything, the harness reduced average token-related usage, as measured in AI Credits, by about 2.3%. Measure changes in contextA change that saves tokens in one Copilot workflow can increase costs in another. For example, a tighter set of file-tool instructions was inspired by positive results in Copilot code review. In a Copilot CLI online experiment, it increased cost, so we did not ship it. By contrast, removing line-number prefixes and selectively compressing output each reduced average prompt tokens per review by roughly 5% in independent evaluations across a large set of Copilot code review tasks using the production model. We detected no material change in the tracked review-quality metrics. These findings are separate from the earlier migration of Copilot code review to the shared file tools , which, together with review-instruction tuning, reduced code review cost by about 20%. Each change needs to be measured in the workflow where it runs. Five lessons for building efficient AI coding agents
None of these changes made the model smarter. They removed work the model never needed to do. The changes described in this post are shipping across GitHub Copilot experiences that use the same underlying harness.
Bring agentic workflows to your terminal |
|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> What began as a personal experiment quickly became a global open source project with extraordinary momentum. OpenClaw is a personal AI assistant that runs on users’ devices and connects with the messaging channels they already use. Started by Peter Steinberger as a weekend project in November 2025, its GitHub repository has grown to approximately 388,000 stars, 81,000 forks, and more than 80,000 commits by August 26, 2026. In this video interview, filmed just six months into the project, creator Peter Steinberger and several OpenClaw maintainers discuss managing a surge of pull requests, rethinking contributor trust and code review, addressing software supply chain risks, and balancing powerful agent capabilities with security. They also share security lessons from the GitHub Secure Open Source Fund and the value of connecting with maintainers facing similar challenges. Watch the full video above, then explore the key lessons below. People in this videoThe following maintainers shared their experiences maintaining and securing OpenClaw.
Here are the top 10 lessons that we took away from the conversation. Lessons 1–3: How AI changed contributions and community1. Pull requests became prompt requestsOpenClaw’s maintainers found themselves managing thousands of pull requests and issues, with some contributors opening hundreds of pull requests at once.
The challenge shifted from attracting participation to finding valuable contributions amid a flood of activity that could overwhelm human review. 2. Keep the door open for new contributorsOpenClaw’s maintainers wanted the project to be welcoming to new participants, whether they were first-time open source contributors, non-developers solving a specific problem, or people using AI agents to help. Rather than dismissing imperfect contributions, they looked for promising ideas and worked with contributors to refine, rewrite, or complete the final changes themselves.
Some of the first-time contributions that were merged came from people without a development background. They used an agent to create a pull request, and worked with maintainers to finish the change.
3. Agents save time but make it harder to sign offThe maintainers described two very different outcomes from the same technology: agents can help people reclaim time, but they can also make it harder to stop working.
Agents are neither good nor bad for work-life balance. But they amplify both the opportunity to do more and the importance of knowing when to step away. Lessons 4-6: How maintainers adapted4. Earn trust by finding where you can add valueThere was no single path to becoming an OpenClaw maintainer. Some contributors arrived through security work, others through integrations or community participation, but the common thread was finding a way to add value and taking ownership.
5. The new trust signal is showing your workAs contribution counts became less informative, the team identified evidence that could help a pull request stand out: agent transcripts, screenshots, testing, and an explanation of the contributor’s thinking.
The important question was not simply whether a human or an agent wrote the code. It was whether the contributor understood the feature and had considered how it interacted with the rest of the project.
6. Maintainers are reviewing agent code with agentsMaintainers increasingly relied on AI tools to help review AI-generated contributions, while also taking a more hands-on approach to improving submitted code.
Lessons 7–9: Security challenges7. Reputation became an attack surfaceContribution history itself could be manipulated. OpenClaw’s maintainers saw people duplicate existing pull requests, and Vincent Koc explains why.
Peter described a company using an automated pull request to promote their product. The team had to identify duplicate work and determine which pull request was the original. The code was not the only thing the project needed to evaluate. Maintainers also had to reconsider the social signals they used to decide what, and whom, to trust. 8. “Safe by default” depends on who you askWhat feels safe to one user may feel unnecessarily restrictive to another. The tradeoff was clear in practice. Tighter workspace restrictions generated user complaints, while fewer restrictions could expose the project to security incidents.
Secure defaults must account for an agent’s capabilities, what users understand, and what a particular environment is prepared to allow. 9. Know who maintains your dependenciesRecent supply chain attacks pushed the maintainers to think more carefully about both the dependencies they relied on and their relationship with the projects behind them.
Lesson 10: How the GitHub Secure Open Source Fund helpedParticipants described the GitHub Secure Open Source Fund as both a security learning experience and a way to connect with maintainers confronting similar, often overwhelming, problems.
The program provided greater awareness of security practices and helped participating maintainers understand how to prompt agents.
Vincent emphasized the value of meeting other maintainers who were experiencing the same challenges of securing open source projects. The program gave participants a community they could tap into and learn from as those challenges continued. Continue the conversationWatch the full conversation to hear how OpenClaw’s maintainers are adapting when contributions scale faster than the human systems used to review, secure, and sustain them. OpenClaw participated in Session 4 of the GitHub Secure Open Source Fund. To learn more, read What 50 open source projects taught us about security in the AI era. Applications for the GitHub Secure Open Source Fund are now open . If you’re maintaining an open source project, apply to learn from security experts, connect with fellow maintainers, and strengthen the security of your project. Head over to the GitHub Community and ask the maintainers what it’s really like building the fastest-growing open source project in GitHub history! Thank you to all GitHub Secure Open Source Fund PartnersTogether, we are helping secure the open source ecosystem for everyone!
Funding Partners:
Alfred P. Sloan Foundation, American Express, Chainguard, Datadog, Herodevs, Kraken, Mayfield, Microsoft, Shopify, Stripe, Superbloom, Vercel, Zerodha, 1Password
Ecosystem Partners
: Atlantic Council, Ecosyste.ms, CURIOSS, Digital Data Design Institute Lab for Innovation Science, Digital Infrastructure Insights Fund, Microsoft for Startups, Mozilla, OpenForum Europe, Open Source Collective, OpenUK, Open Technology Fund, OpenSSF, Open Source Initiative, OpenJS Foundation, University of California, OWASP, Santa Cruz OSPO, Sovereign Tech Agency, SustainOSS
Looking for practical security steps you can take for your project? Set up the security baseline for your project in one minute > |

|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> I might be biased, but I think Dependabot is pretty amazing. It helps keep my projects up to date, ensuring I’m always using secure libraries. But because there’re frequently new vulnerabilities, there’re frequently new pull requests from Dependabot. Sometimes it’s a minor version bump. Sometimes it’s a major version upgrade. Sometimes everything will work just fine. And sometimes… well, every single developer has been caught by a breaking change. How can we best triage these pull requests? The work isn’t particularly difficult per se, but it certainly is repetitive. It’s the perfect task to offload to Copilot! With GitHub Copilot app automations , you can hand off that first round of review. Instead of manually inspecting every Dependabot pull request, you can create an automation that reviews open pull requests, groups them by risk, verifies CI status, and delivers a summary before your day begins. Follow the steps below to build a daily Dependabot triage automation. Step 1: Create a new automationFrom the GitHub Copilot app, create a new automation . You’ll configure two things first:
Available trigger options include:
For recurring maintenance tasks like Dependabot reviews , a daily schedule is often a good choice. For example, you might schedule it to run before your workday begins so the results are waiting when you log in. You can also choose whether the automation runs in the cloud or on your local machine. Step 2: Describe the task in natural languageNext, tell Copilot what you want it to do. For example:
Because the prompt uses natural language, you can customize it to match your team’s workflow. Step 3: Select the repositoryChoose the repository or project the automation should analyze. Once you’ve selected the repository, create the automation. If you want to test it immediately instead of waiting for the scheduled run, choose Create and Run . Step 4: Review the resultsWhen the automation finishes, Copilot returns a summary instead of a list of individual pull requests. For example, it might:
Rather than interrupting your morning with dozens of small decisions, you can quickly identify which updates are ready to merge and which deserve closer attention. Step 5: Continue the work in a Copilot sessionIf one of the updates requires additional work, you can continue directly from the automation results. For example, if the summary identifies a major framework upgrade, you can start a new Copilot session from the results and ask Copilot to help complete the migration. Because the session starts with the automation’s context, you don’t have to gather the information again. Review previous automation runsEvery automation run is saved, making it easy to see:
Having a history of each run makes automations transparent. You can always review what happened instead of treating them as a black box. Turn repetitive work into background workDependabot triage is a good example of the kind of recurring task that’s well suited for automation. You describe the workflow once, choose when it should run, and let Copilot perform the repetitive steps automatically. If you’re just getting started with automations, begin with a task you already perform on autopilot. Let Copilot handle the routine work so you can spend your time on the decisions that require your expertise. Ready to automate your next recurring task? Create your first automation in the GitHub Copilot app > |
|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> A language model can perform well on a clean benchmark and still struggle with the cases that matter in production. Benchmarks and curated datasets are useful when prototyping an LLM-based system. They help teams compare models, test an initial prompt, and determine whether an idea is technically plausible. But as a system moves closer to production, the evaluation problem changes. Real inputs are often ambiguous. Labels may be inconsistent. Important context may be missing or truncated. The evaluation set may not reflect the production distribution. Edge cases that rarely appear in benchmarks can become common sources of failure. Even when offline metrics improve, those results may not translate cleanly into production behavior. We encountered these challenges while evaluating an LLM-based system designed to reduce false positives in GitHub secret scanning. Secret scanning identifies credentials such as tokens and keys that may have been committed to a repository. Because some candidate strings resemble secrets, but don’t actually represent real credentials, developers may spend time investigating alerts that don’t require remediation. Rather than determine whether an LLM could classify a string correctly, we needed to understand whether the system could reduce noisy alerts while preserving enough recall to remain safe for a security workflow.
In this post, we share the practices that helped us move from promising prototype results to production. The lessons apply broadly to LLM-powered systems in code analysis, developer tools, security, data analysis, and other production workflows.
1. Start with the product decision, not the modelWhen an LLM system doesn’t perform as expected, the first instinct is often to adjust its technical components. Teams may rewrite the prompt, add context, introduce another reasoning step, adjust the surrounding pipeline, or switch models. Before making any of these changes, they should define the decision the evaluation is meant to support. For our secret-scanning work, we asked: Can the system reduce false positives while preserving enough recall to be safe in a production security workflow? To answer this question, teams must decide which mistakes are acceptable, which metrics should drive the product decision, and which guardrails must remain within their defined thresholds. In secret scanning, incorrectly suppressing a real credential can be more consequential than asking a developer to review an additional alert. We therefore did not treat precision and recall as equally interchangeable metrics. Our primary objective was to reduce false positives and improve precision. Recall served as a safety constraint: an experiment could advance only if any decrease remained within a predefined acceptable range. This gave us a clear way to evaluate tradeoffs. We selected the configuration that achieved the strongest false-positive reduction while satisfying the recall requirement and meeting our operational guardrails. We organized the evaluation criteria into three levels: Primary outcomeThis measured the user benefit we were trying to improve:
Safety constraintThis prevented an apparent improvement from introducing unacceptable security risk:
Operational guardrailsThese determined whether the result was practical to deploy:
This distinction prevented us from treating every metric as interchangeable. A change that reduced false positives but significantly lowered recall wasn’t automatically an improvement. Neither was a change that improved quality while making the system too slow, expensive, or difficult to integrate.
Consider two hypothetical experiment results:
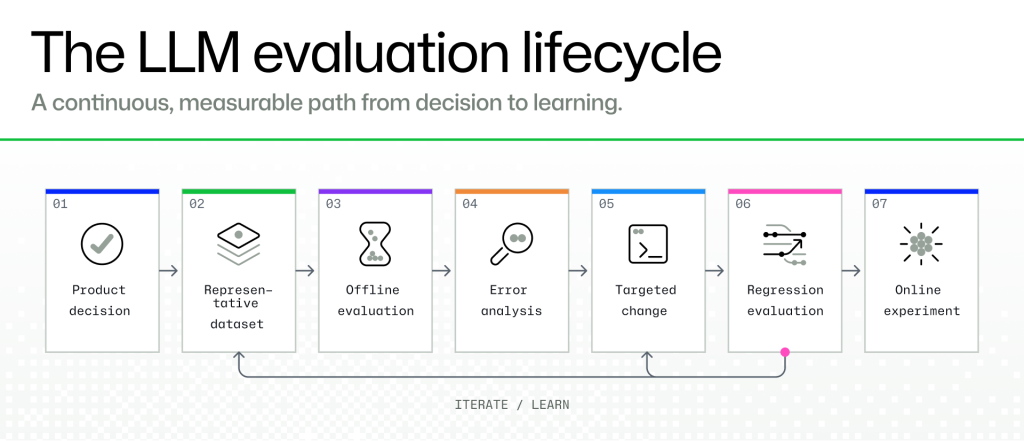
Experiment A may look stronger if precision is viewed in isolation. Experiment B is more aligned with the product goal because it improves the developer experience without violating the recall guardrail. Before evaluating an LLM system, decide what success means for the user and which guardrails the system must respect. We want to generate evidence that supports a product decision. 2. Treat offline evaluation like integration testingAn LLM-based system continues to change after its first successful evaluation, so evaluation should not be a one-time exercise. Teams revise prompts, adopt new models, change how inputs and context are constructed, and refine the surrounding business logic. Any of these changes can improve the system, introduce a regression, or shift its behavior in an unexpected way. For that reason, we treated offline evaluation similarly to an end-to-end integration test. We reran it whenever we made a meaningful change to the prompt, model, input construction, or broader system logic. The evaluation also needed to be repeatable enough that each new result could be compared against a known baseline. For every run, we recorded the prompt, model, dataset version, and system configuration. This made it possible to answer questions such as:
Without this discipline, teams can easily compare results generated under different conditions and attribute an improvement to the wrong change. Change one major variable at a timeRepeatability alone is not enough. Experiments also need to be designed so that the cause of a result is clear. We changed one major variable at a time and compared each run against a known baseline. For example, we evaluated a prompt revision separately from a model upgrade before testing the two together. This mattered because even small prompt changes could shift model behavior, while a model upgrade could affect quality, cost, latency, or output consistency. If both changed in the same experiment, we would not know which one caused the improvement or regression.
We treated prompts and evaluation configurations like code. We versioned them, recorded what changed, kept previous configurations reproducible, and made rollback possible.
The values in the evaluation run tracking table above shown are hypothetical and included only to illustrate how evaluation runs can be tracked and compared. Test model upgrades regularlyWhen an LLM system underperforms, developers often respond by adding more instructions to the prompt. Sometimes that helps, but not always. For example, the prompt may be carrying complexity that comes from the model itself. A stronger model may perform better with a simpler prompt than an older model does with extensive tuning. Simpler prompts are also easier to understand, test, and maintain. Model upgrades still need careful evaluation. A new model may improve performance in one category while introducing regressions elsewhere. It may also affect cost, latency, output formatting, or compatibility with the existing pipeline. The evaluation process should be inexpensive and repeatable enough that testing a new model becomes routine. Any meaningful change to the prompt, model, or pipeline should go through offline evaluation before reaching production. 3. Keep offline evaluation close to productionAn offline evaluation is only useful when it resembles the task the system will perform in production. In a secret-scanning workflow, the model is rarely evaluating one clean, isolated value. It may need to assess a specific candidate alongside surrounding code and other information that is relevant, incomplete, or potentially distracting. Differences in how that information is presented can materially affect the result. Our offline evaluation therefore needed to preserve the important characteristics of the production task, including:
Even small differences can skew the results. A cleaner dataset may exclude ambiguous cases, provide more complete context, or remove nearby values that could distract the model. Consider a simplified example:
Suppose This kind of failure is easy to miss when evaluation examples contain only one obvious candidate. It surfaced because the offline evaluation preserved some of the ambiguity and distractions found in real secret-scanning workflows. The closer the offline pipeline is to the production pipeline, the more useful the evaluation becomes. When the two differ, a strong offline score may simply reflect an easier problem than the one being deployed. 4. Treat production labels as signals, not unquestionable truthProduction data can make an evaluation more representative, but its labels often capture workflow outcomes rather than reliable ground truth. A dismissed or resolved secret-scanning alert, for example, does not necessarily represent a false positive. A developer might resolve an alert because:
These outcomes may look similar in product data while representing different ground-truth states. Before using production labels, ask:
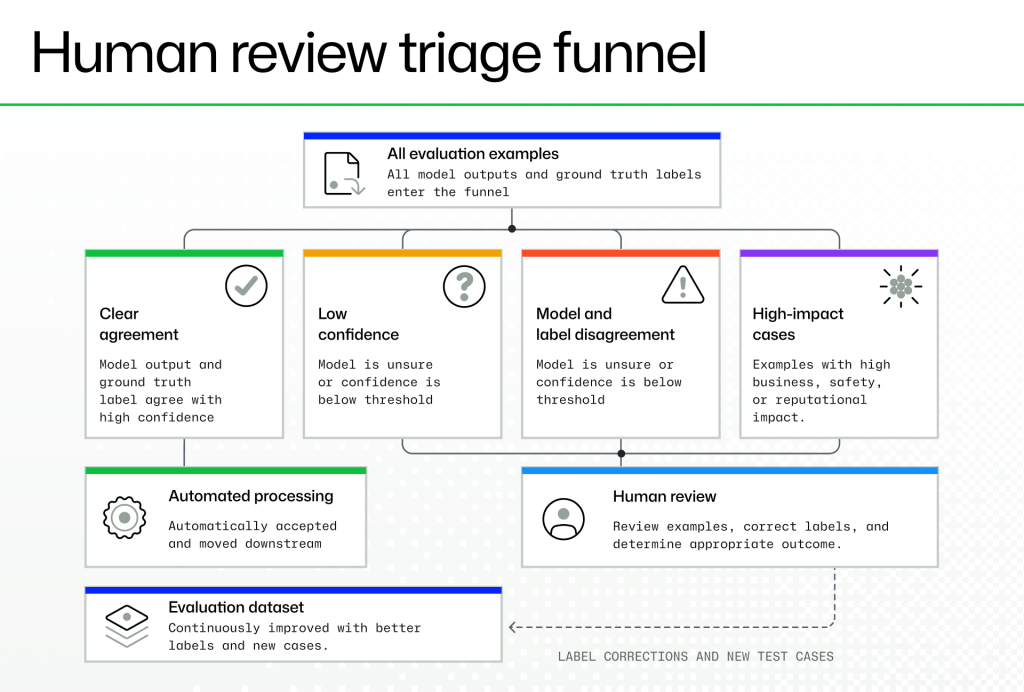
For important or ambiguous subsets, you may need to complete a manual review. You’re not trying to eliminate every imperfect label, but you need to make sure the evaluation data is accurate enough to support the decision being made. 5. Use synthetic and open datasets to fill coverage gapsRepresentative production data may be limited, sensitive, or unavailable early in development. Synthetic examples, academic benchmarks, and open datasets can help developers bootstrap an evaluation and expand coverage, but these examples should supplement rather than stand in for production-like data. With that in mind, synthetic examples can greatly help fill in the gaps for testing cases that are rare or difficult to collect, such as ambiguous inputs, missing context, unusual formatting, and underrepresented failure patterns. A list of credential strings, for example, can test whether a model recognizes common formats, but it cannot fully evaluate how the model reasons about a candidate within real code. We adapted external examples to match our task and reviewed labels that did not align with our product definition. We also used realistic failure patterns to create targeted synthetic cases involving nearby credential-like values, test code, placeholders, indirect references, and missing context. 6. Use error analysis to find what aggregate metrics hideAggregate metrics tell you whether a system improved overall. Error analysis tells you what to change next. A higher precision score doesn’t reveal whether the remaining errors come from ambiguous inputs, poor prompt framing, missing context, noisy labels, or a narrow dataset. To understand those problems, inspect the failures. We reviewed samples of false positives and false negatives and grouped them by their likely source: the model, prompt, input, pipeline, dataset, or label. The recurring issues included several already discussed, such as reasoning about the wrong candidate, missing context, and labels that did not match the evaluation definition. Each category suggested a different response. Reasoning about the wrong value pointed to prompt or input framing, missing evidence pointed to context construction, and incorrect labels required data cleanup. Repeated domain-specific ambiguity could indicate the need for a clearer product policy or a dedicated evaluation category. Manually reviewing dozens or hundreds of examples takes time, but it often leads to faster progress. Once a recurring failure pattern is clear, the team can make a targeted change and measure whether it solved the problem. A useful question for each error is: Did this failure come from the model, prompt, input, pipeline, dataset, or label? That classification turns a vague quality problem into a concrete engineering task. 7. Use LLM-as-judge to focus human reviewReviewing every evaluation example manually may not scale. LLM-as-judge can reduce that burden by classifying clear cases, identifying potentially mislabeled examples, and prioritizing ambiguous cases for human review. Because the judge can also make mistakes or agree with another model for the wrong reason, its output should be treated as another prediction rather than ground truth. A safer pattern is to use the judge for triage:
Used this way, the judge concentrates human attention on the cases where review is most likely to change the outcome.
8. What secret scanning taught usOur goal was to reduce false positives while preserving recall in a security-sensitive workflow. Offline evaluation gave us a controlled way to compare prompt, model, input, and pipeline changes before beginning online experimentation. Through repeated evaluation and targeted error analysis, we reached a 95% reduction in false positives on the evaluated offline dataset while keeping recall within our defined guardrail. More importantly, we understood how the result had been produced: the evaluation reflected the production task more closely, changes were measured against reproducible baselines, and the remaining failure patterns were documented. Offline evaluation did not prove how the system would behave in every production scenario. It provided enough structured evidence to justify moving to online experimentation with clearly understood risks and guardrails. Checklist: Before moving an LLM system toward productionUse this checklist to assess whether your evaluation provides enough evidence to move the system forward. Work through each section to confirm that the goals, data, experiments, and remaining production risks are clearly understood. Product Goals
Data and Labels
Evaluation Rigor
Error Analysis and Production Readiness
Evaluate before you trustAs LLM-based systems move into production, evaluation should become part of the regular engineering workflow. A strong offline evaluation can show whether the product goal has been met under representative conditions, where uncertainty remains, and whether the system is ready for a controlled production rollout. Production uncertainty is unavoidable. Evaluation makes it visible, measurable, and manageable. The post How to evaluate LLMs before production appeared first on The GitHub Blog . |
|
html PUBLIC "-//W3C//DTD HTML 4.0 Transitional//EN" "http://www.w3.org/TR/REC-html40/loose.dtd"> More than one in four images on the web’s most popular home pages have alt text that’s missing, vague, or copied from adjacent images.
That’s from WebAIM’s 2026
WebAIM Million
report, which found that alt text,an HTML attribute containing text describing the content of an image, was missing on 16.2% of images across the top million home pages. Among the images that
did
have alt text, another 10.8% provided an undescriptive attribute, such as
While automated tooling reliably flags missing alt text, it isn’t as good at fixing poorly written alt text. Most alt text checkers test whether an accessible name for an image exists, not whether the provided alt text says anything useful about the associated image, and that’s a deliberate design choice: a quality-oriented rule with false positives is a rule teams switch off. So We built an alt text plugin for the GitHub Accessibility Scanner to help improve your alt text. This post covers where we drew the line between what a checker can prove and what it can only suspect, why our worst bug turned out to be a layout problem rather than a parsing one, and what changed once we let a model into the loop. If you’re building automated checks of your own, for accessibility or otherwise, the tradeoffs should transfer. Proving a string is wrong without seeing the picturePresence of alt text is an objective fact; the attribute is there or it isn’t. Quality is often a judgment call. A machine can’t prove whether a sentence adequately describes a picture in context from markup. However, not all quality is subjective. There’s several checks you can perform based on the alt text alone, with no need to consult the image content:
Every one of those is a claim about a string, and that became our dividing line. Five deterministic rules run by default which need no credentials for running AI models or network calls. One opt-in rule calls a model with provided image content and surrounding context, for judgments an alt text string can’t support on its own.
First, we had to determine which images to judge on a scanned webpage. We use Playwright’s role-based locator rather than So, how strict should it be? A quality checker lives or dies on false positives, so we chose closed sets over clever heuristics. The vague-alt rule normalizes a string, then checks it against a curated list of words that carry no information on their own. It fires only on an exact match:
Rules this literal miss plenty of bad alt text. We took the miss over the false positive, because a reliable checker that developers enable beats one that gets switched off. Repetition is a layout problem, not a DOM problem
Repeated alt text presented an interesting problem. Picture a row of five star-shaped icons that each say Our first version walked the images in document order and flagged any run sharing the same normalized alt. It caught things it shouldn’t have. For example, a footer “GitHub” logo and a header “GitHub” logo might sit next to each other in the extracted list but nowhere near each other on screen, so nobody experiences them as a group. What matters is where images land on screen, not where they sit in the markup. So the rule now checks page layout, and only extends a run when the gap between two bounding boxes is small compared to the boxes themselves:
Two details worth noting:
Getting a model to act like a reviewer, not a critic
Deterministic rules only need the alt string. Anything smarter needs to know what the page is about, and none of that is tracked by the image element. Whether
In our optional The link signal matters most, because when an image is a link’s only content, its alt becomes the link’s accessible name. The right alt then names the destination instead of describing the picture. One caution: The plugin only records that an image sits inside a link. We don’t check whether it’s the link’s only content, which is the part that actually turns alt into a link name. So right now both cases look identical to the model. That context, the alt, and the image go to a vision model through GitHub Models . Our failure modes were rarely the model misreading a picture. They were the model having opinions. Given perfectly good alt text, our first version of the checker would suggest different alt text, because “could this be better?” is a question a language model always answers yes to. Every image becomes a finding, so the signal disappears. Three changes fixed it:
None of that makes the model unfailingly correct. It makes it consistent enough to iterate against. The repository carries an offline grading harness built from published teaching material: WebAIM , the W3C images tutorial , and POET . The rule and the harness share one prompt, so what you tune offline is what runs in CI. That harness only tests the model’s judgment, though, not the whole pipeline. A case can score perfectly there and never reach the model in a real scan. Sending images to a model is a privacy and cost decisionThe moment a check calls an external model with webpage data, it stops being just a lint rule and requires careful data flow design. A few things follow from that:
One caution, because that list is easy to over-read: findings still carry the real page URL and original HTML into the scanner’s normal reporting pipeline. That’s on purpose, since you can’t fix an image you can’t locate. Redaction narrows what reaches the model and the logs, not what lands in your own issues. And if you set up Azure AI Vision credentials, an optional OCR pre-pass sends image bytes to a second place. Nothing requires Azure, but a data-flow review needs to cover both paths. Cost follows the same shape. In the common case this is one model call per image per scan, which on an image-heavy site dominates the cost of the whole run. That’s reason enough to put it on a schedule rather than on every commit. What this still can’t do
What we’d tell you if you’re building something similarSeparate what you can prove from what you can only suspect, and give them different defaults. Checks that prove something should be cheap, predictable, and on by default. Checks that only suspect something should be opt-in, and should read as a suggestion rather than a verdict. Then, ask what the user experiences rather than what the DOM says. Every gap still open in this plugin has that second shape. We record that an image is inside a link, not that it is the link. We read an attribute, not a computed name. That distance is the real boundary, and a better model doesn’t close it. Deciding what the functionality of an image is for a user who can’t see it still requires human judgment. What automation buys you is making sure that human is giving the right images a second examination. Try the alt-text plugin in your accessibility scanning workflow. If it tells you the wrong thing, please report it. Open an issue with the finding and, if public, a link to the affected page. The post Your alt text passes automated checks. That doesn’t mean it’s any good. appeared first on The GitHub Blog . |
Distributed by aarss.com.